~/blog/agent-tooling-serena-graphify-obsidian-setup
One repo, three layers: Serena, Graphify and Obsidian for agents
A step-by-step setup wiring Serena, Graphify and an Obsidian vault under one AGENTS.md: commands, file layout, git decisions and how to verify each layer.
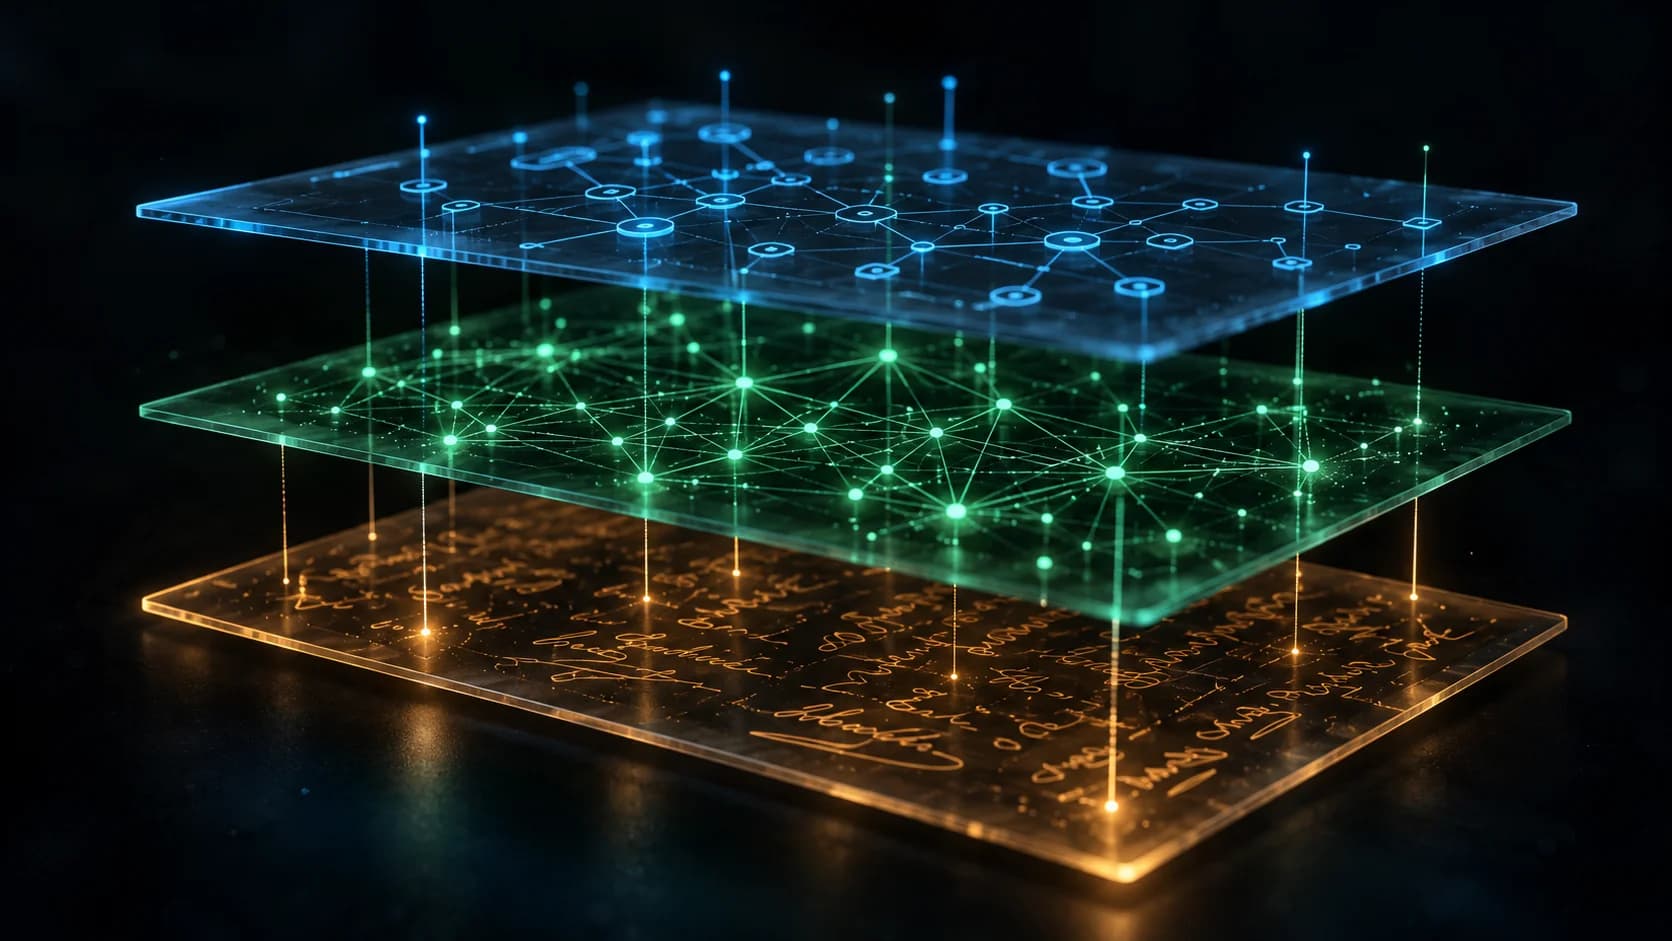
A coding agent is only as good as what it can see. Out of the box it sees the files you point it at, it greps when it wants to know where something is used, and it forgets everything the moment a session ends. The decisions behind the code, the constraints nobody wrote down, and the reason the last refactor stopped halfway all live in someone's head. I have spent months adding three layers to the repositories I work in, each answering a different question: Serena for the structure of a symbol, Graphify for how things relate across files, and an Obsidian vault for why the code is the way it is. This article describes that setup exactly: the commands, the files they create, the one rules file that ties them together, and the git decisions you have to make. It also says what each layer does not do, because a setup nobody can explain is worth less than a smaller one everybody understands.
The three layers and the question each one answers#
Before any command, decide what each layer is for. Most of the confusion I see comes from one tool being asked a question that belongs to another.
| Layer | Tool | Answers | Does not answer |
|---|---|---|---|
| Symbols | Serena | Where is this symbol defined, who calls it, what implements it, what does the language server report | How modules relate at the architecture level, or why the code exists |
| Relationships | Graphify | Which files and communities depend on each other, the shortest path between two concepts, the hubs of the codebase | Exact signatures and types, which Serena reads from the language server |
| Notes | .context/ in the repo, surfaced in an Obsidian vault | Why a decision was made, what the status is, what is blocked, what comes next | What the code does right now |
The rule that makes the setup work is an ordering rule, and it goes into the repository's rules file later in this article. Symbol questions go to Serena. Structural questions go to Graphify, before any broad grep. Why questions go to the notes. Raw grep is the last resort.
The shape of the result#
When the setup is finished, one repository has these pieces:
repo/
  AGENTS.md              # the one rules file every tool reads
  CLAUDE.md              # a thin pointer: @AGENTS.md
  .serena/               # Serena project config, symbol cache, memories (git-ignored)
  graphify-out/          # the graph: graph.json, GRAPH_REPORT.md, query artefacts
  .graphifyignore        # only if the repo has paths git tracks but the graph should skip
  .context/              # project notes: Overview, Status, Decisions, Tasks, Notes
    Project Overview.md
    Project Status.md
    Decisions/
    Tasks/
    Notes/
    _System/Context Instructions.md
  .git/hooks/post-commit      # keeps graphify-out/ current
  .git/hooks/post-checkout    # same, on branch switches
Outside the repository, the vault holds one symlink per project. The symlink points at the repository's .context/ folder, so the notes live with the code and appear in the vault without being copied:
<vault>/Areas/<project> -> <repo>/.contextThe vault also keeps a registry note that lists each project and the observed state of each tool. The state is recorded as observed, not assumed, which matters later when something stops working.
The vault: PARA as the skeleton#
The repository layers only work if something holds them together, and that something is an Obsidian vault organised with PARA, Tiago Forte's scheme of Projects, Areas, Resources and Archives. I add an Inbox in front of it and a _System/ folder behind it. The vault is the index, and the repositories hold the detail. I covered why the vault holds the memory a coding agent otherwise loses between sessions in Why Claude Code Loses Context, and How Obsidian Fixes It.
What each folder is for#
PARA sorts notes by how soon you act on them, not by topic. The question to ask is "how soon do I act on this?", not "what is this about?". The folders answer it like this:
| Folder | Holds | Test | Ends when |
|---|---|---|---|
Projects/ | An endeavour with a concrete outcome and a possible end | "This is finished when ___" can be written | It ships, is abandoned, or degrades into an Area |
Areas/ | A long-term responsibility with a standard to keep | No sentence of the form "finished when ___" exists | Never. It is kept at its standard or allowed to slip |
Resources/ | Reference material with no active commitment | It is pulled from, not worked on | Never, but it can be archived |
Archives/ | Inactive items from the other three | Shipped, abandoned, or no longer relevant | Never moves back automatically |
Inbox/ | Everything unsorted, captured cheaply | Undecided is a valid state | Emptied at each review |
_System/ | The vault's own machinery: rules, workflows, registry, indexes, templates, logs | Not a note about the world | Never |
The decision order is short and it is the one to memorise:
- Is there a concrete outcome and an end? Then it is a Project.
- Is it a standard to maintain with no end? Then it is an Area.
- Is it reference material that supports either? Then it is a Resource.
- Is it none of these yet? It stays in Inbox and the reason is written down.
An Area is the usual home for a personal site kept to a standard. A client delivery with a finish line is a Project. The same repository can move between the two, and when it does the move is a symlink move, not a note move. The registry procedure for that is described below.
What lives in _System/#
_System/ holds the parts an agent reads before it writes anything:
Operating Manual.md: the PARA definitions and the decision order above.Agent Rules.md: the numbered rules for any agent working in the vault. This is the one to read first.Capture Workflow.md: how information enters the vault and when an item becomes a project.Review Workflow.md: the cadence for keeping the vault true.Project Registry.md: one entry per repository-backed effort, with paths and observed tooling state.Dashboard.md: the entry point, linking into PARA, the system notes and the live list of efforts.Decisions Index.mdandNotes Index.md, plusResources Index.md: generated indexes, searched before deciding or researching.Templates/:Project.md,Area.md,Decision.md,Task.md,Resource.md,Meeting.mdandDaily Note.md.Logs/: session logs for work done on the vault itself, named by date and topic.bin/build-indexes.sh: the script that rebuilds the three generated indexes.
Every folder also has an index.md, which is the navigation page the Dashboard links to. Inbox/index, Projects/index, Areas/index, Resources/index and Archives/index are the five entry points.
The vault root has its own AGENTS.md, the same pattern as the repositories. It holds the vault's non-negotiable rules and the frontmatter schema, and a CLAUDE.md that only imports it. Every agent that opens the vault reads the same file.
The frontmatter schema#
Every note starts with flat YAML, with no nested objects. The schema is the part that lets the indexes and the Dashboard work without a database:
---
date: YYYY-MM-DD
description: "about 150 characters, enough to scan without opening the note"
tags: [flat, list, no-hierarchy]
type: project | area | resource | decision | task | meeting | daily | session-log | inbox
status: active | in-progress | blocked | done | superseded | archived
---
Extra fields depend on the type. A project or area carries path: (the absolute repository path) and context: (the absolute path of its .context). A decision carries date-decided: and a one-line outcome:, and when it is replaced it gets status: superseded and superseded-by: pointing at the new note. A task carries owner:, due: and parent:. A session-log carries project: and branch:.
The description is the field that matters most. It is what an index prints, and it is what an agent reads when it decides whether a note is relevant. A description that says "notes" is wasted. A description that says what was decided and why can be found again in a year.
Statement labels#
Every non-trivial claim in a note carries its kind. The labels are the ones in Agent Rules.md rule 5, and they are the difference between a note that can be trusted and one that merely reads well:
| Marker | Meaning |
|---|---|
FACT | Verified, with a source |
DECISION | A choice that was made |
HYPOTHESIS | Plausible and unverified |
TASK | Something to be done |
QUESTION | Unresolved, and blocking something |
RECOMMENDATION | The agent's suggestion, not yet accepted |
The reason for the labels is rule 4, "never launder inference into fact". An agent that writes a guess in the same voice as a verified measurement has created a document that will be trusted later by someone who does not know which sentence was which.
Step zero: decide two things before you touch anything#
Two questions shape the setup, and both are easy to skip.
Is this a project or an area? A project has an outcome and a possible end date. An area is an ongoing responsibility with no end. The answer decides where the vault symlink lands, under Projects/ or under Areas/, and it changes how a future reader interprets the notes. I put a personal portfolio under areas, because it has no finish line. A client delivery goes under projects, because it does.
Is the repository public? This decides what can be written into .context/ and into Serena's memories. Both are plain files in the repository. If the repository is public, every note in them is public, and so is every line of a memory. Nothing secret, no client detail, no credential belongs in either place.
Check what tools are on the path before you start. The setup assumes serena and graphify are installed and that Claude Code is configured. If either is missing, install it as a separate decision. The setup below does not install global tools for you.
Layer one: Serena#
Serena is a symbol layer. It runs a language server, indexes symbols into a cache, and gives the agent tools for finding definitions, references, implementations and diagnostics. It is registered once, globally, and it resolves the project from the working directory.
Register the MCP server, once#
Check whether it is already there:
claude mcp list | grep -i serenaOnly if the output shows no serena entry, register it:
serena setup claude-codeA second registration is a duplicate configuration, and it produces two servers that fight over the same project. If the entry exists but shows Failed to connect, do not re-register. Report the failure and fix the transport separately. The project configuration and the symbol index do not depend on the transport.
Create the project configuration#
serena project create "$REPO" --name "$NAME"Serena infers the language. Pass --language only when the inference is visibly wrong, and repeat the flag for a polyglot repository. Do not pass --index here. Keep indexing as its own step, so that a failure is attributable to one command.
Index and check#
serena project index "$REPO"
serena project health-check "$REPO"
Indexing writes the symbol cache under .serena/cache/. It is safe to rerun, because it refreshes rather than duplicates. On a large repository it takes minutes, so run it in the background and read the result when it finishes. The health check is the real test. A failing line from it means the symbol tools will not work, and the honest response is to quote that line in your notes rather than to proceed anyway.
Seed the memories#
serena memories initialize "$REPO"Then write the onboarding memories. If the Serena MCP server is connected, use its own onboarding flow first: check whether onboarding was performed, run it if not, and write the memories it produces. If the server is unreachable, write them from the CLI, and only what you verified in the repository:
serena memories write core --file /tmp/core.md "$REPO"The conventional set is core, tech_stack, suggested_commands, conventions and task_completion. Write the ones you can ground in the repository, and leave out the rest. The rule that matters most is in suggested_commands: copy the commands from the manifest, exactly, and never invent one. If there is no test script, task_completion should say there is no test suite and that changes are verified by hand. An agent that is told that does not spend a session looking for a runner that does not exist.
Verify the memory layer:
serena memories list "$REPO"
serena memories check "$REPO"
Git for Serena#
The .serena/ directory holds a machine-local cache and repository-describing memories. I keep it git-ignored. The cache must never be committed, and the memories are small enough that committing them is optional. Decide once and write the decision down, because the question comes back every time someone clones the repository.
Layer two: Graphify#
Graphify builds a graph of the code: nodes for files and symbols, edges for the relationships between them, and communities of nodes that cluster together. The useful outputs are the query commands, which return a scoped subgraph for a question rather than a wall of text.
Extract, code only#
graphify extract "$REPO" --code-onlyThe --code-only flag runs local AST extraction, skips documents, papers and images, needs no API key and costs nothing. Use it for onboarding. Semantic extraction, with --mode deep or without the flag, reads documents and infers edges that an AST cannot see, and it spends API tokens. Treat it as a separate decision with its own cost, not as part of setup.
Communities come out named Community N until an LLM pass names them. Those placeholder names are not a defect. The query, path and explain commands work without them. Naming costs tokens, so ask before running it:
graphify label "$REPO" --missing-only --backend=claudeIgnore rules#
Graphify honours .gitignore by default, which already excludes build output and dependencies. Add a .graphifyignore only for things git tracks but the graph should not contain, such as vendored code, fixtures, generated clients or large data dumps:
# .graphifyignore
**/__fixtures__/**
**/generated/**
Do not write a file full of patterns the repository does not contain. A missing .graphifyignore is a perfectly valid outcome, and many repositories need none.
The rules in AGENTS.md#
Use Graphify's own installer to write its section into AGENTS.md, so the block stays consistent with the tool version and can be removed by its own uninstaller:
cd "$REPO" && graphify codex installCheck first whether a graphify section already exists. A second block is a duplicate configuration, not an upgrade. If the installer's block lands next to a hand-written section, keep the installer's version and remove the overlap by hand, and say so in your notes.
The Claude-specific installer also exists: graphify claude install writes a section into CLAUDE.md and adds a PreToolUse hook. In a repository where CLAUDE.md is only a pointer to AGENTS.md, this duplicates the rules. Take it only when you actually want the hook.
Git hooks that keep the graph current#
cd "$REPO" && graphify hook install
graphify hook status
The hooks are post-commit and post-checkout. They rerun the same AST-only extraction after each commit and each branch switch, so the graph never drifts far from the code without anyone remembering to run graphify update. The installer also registers a merge driver that union-merges graph.json, which removes most of the conflict pain when two branches both touch the graph.
Check the status before installing. If the hooks are already present, leave them alone. Skip the installation only when a hook manager owns .git/hooks, which is what husky, lefthook and pre-commit do. In that case the installation would overwrite another tool's hooks. Stop, report the conflict, and decide which tool keeps the hook slot. Do not let a graph tool silently replace a linter.
Keeping it current, and the dirty tree#
After code changes, the hook does the work. Run the update by hand when you have not committed:
graphify update "$REPO"The --force flag overwrites graph.json even when the rebuild has fewer nodes. That is the right call after a refactor that deleted a lot of code, and a destructive one otherwise. Use it deliberately.
A dirty graphify-out/ after a hook run is expected. Do not treat it as a reason to distrust the graph, and do not hand-edit anything under it. The output is machine-generated, so you cite it and never author it.
Git for Graphify#
graphify-out/ is generated, and it is still worth committing. It travels with the repository, so any agent that clones it gets the graph without re-extracting, and the merge driver handles conflicts on shared branches. I commit it. The decision is yours, and it is worth writing down with its reason.
Layer three: the notes and the vault#
The notes layer is where the setup stops being about tools and starts being about memory. A coding agent reads the code faithfully and forgets the reason for the code between sessions. The .context/ directory is where the reason goes.
Create the structure#
.context/
├── Project Overview.md
├── Project Status.md
├── Decisions/
├── Tasks/
├── Notes/
└── _System/
    └── Context Instructions.md
Project Overview.md holds the identity of the project, its tooling state with the exact commands in use, the goal, the scope, the completion criteria, the key decisions, the risks and the next steps. The rule for the first version is strict: do not invent project content. Goal, scope and completion criteria stay as _To be filled in._ until they can be read from the README, the package metadata or existing documents. A placeholder that tells the truth is more useful than a plausible sentence that was never checked.
Project Status.md holds the current state, the last update, the achievements, the blockers, the risks and the next steps. Achievements can be summarised from git log --oneline -15, labelled as coming from history. Everything else starts as _None recorded._.
_System/Context Instructions.md tells any agent how to use the directory. It says what to read first, where each kind of note goes, which statement labels to use (fact, decision, hypothesis, task, question, recommendation), which artefacts are generated and must not be edited, and where the scope of the project ends. An agent that reads that one file knows how to behave in the rest of the directory.
Link it into the vault#
Create the symlink without touching what is already there. If the target path exists, stop and read it. Never remove a file to make a link fit:
LINK="<vault>/Areas/<project>"
if [ -e "$LINK" ] || [ -L "$LINK" ]; then
  ls -ld "$LINK"; readlink "$LINK"
else
  ln -s "$REPO/.context" "$LINK"
fi
readlink "$LINK"
Then read the link back and compare the resolved paths. A mismatch means something is wrong, and it is a stop condition, not a rename.
Register the project in the vault's index. The entry records the project path, the local context path, the vault location and the observed state of each tool. Write the state you saw, not the state you intended:
- [[Areas/<project>/Project Overview|<project>]]
  - Project path: `<repo>`
  - Local context: `<repo>/.context`
  - PARA: `Areas/<project>` (symlink to the local context)
  - Graphify: initialized, code-only extraction, git hooks installed
  - Serena: initialized, health check passed
  - Status: active
Use the path form of the wikilink. A plain [[project]] does not resolve, because the symlink is a folder, not a note. After registering, check the vault for broken links and broken symlinks, so you know the new entry did not orphan anything.
Repository rules for the notes#
The repository's AGENTS.md gets a project-context section that tells agents where the notes are and when to update them:
## Project context

Project notes live in `.context/` next to the code, symlinked into the Obsidian vault.

Before making changes, read:
- `.context/Project Overview.md`: charter, paths, tooling state
- `.context/Project Status.md`: current status, blockers, risks, next steps
- `.context/_System/Context Instructions.md`: where notes go and how to label statements

After a substantial change, update `.context/Project Status.md`. Record decisions as one note
per decision under `.context/Decisions/`, with a date and a reason.
Two more lines do most of the work. The first sends anything that would help on a different project to the vault's general resources, because a note inside a project dies with the project. The second says that before recording a decision, the agent searches the vault's decision index for prior decisions on the same topic, and either follows them or supersedes them by name. Without that line, an agent will happily record the opposite of a decision you made two years ago in another repository, and nothing will tell you.
Recording decisions#
A decision note is short and dated, and it has three parts: what was decided, why, and what it replaced. Keep one decision per file. The onboarding itself is a decision worth recording, because it answers questions a future reader will have: why the project is an area and not a project, why the hooks were installed or left out, and what was deliberately not run, such as semantic extraction or community naming. Write it in Decisions/ on the day you do the setup.
One rules file for three tools#
Three installers have touched AGENTS.md: Graphify's, the notes section, and whatever you write by hand. The result must be one coherent file with no duplicated blocks, for the same reason I wrote up in CLAUDE.md and AGENTS.md: instructions a coding agent does not have to guess at. Before you finish, search it:
grep -n -iE '^#|graphify|serena|\.context' AGENTS.mdThen make sure it covers all three layers, appending only what is missing. Do not restate what the Graphify installer already wrote. Finally, add the ordering rule that ties the layers together:
## Which tool for which question

- Structure of a symbol (definition, callers, implementations, diagnostics): **Serena**.
- How things relate across files (architecture, dependencies, what X touches): **Graphify**,
  using `query`, `path` and `explain` before any broad grep.
- Why something is the way it is (decisions, constraints, status, open questions): **`.context/`**.
- Raw grep is the last resort, not the first move.
CLAUDE.md stays a thin pointer, so that Claude Code and every other tool read the same rules:
# CLAUDE.md

Guidance for Claude Code in this repository. All substance lives in `AGENTS.md`.

@AGENTS.md
If CLAUDE.md already holds substance, move it into AGENTS.md in a separate commit with the diff shown first. Do not move it silently.
Git decisions to make once#
Three directories need an explicit answer, and each answer should go into a decision note:
.serena/: the cache is never committed. The memories are a judgement call.graphify-out/: committed, so clones get the graph without re-extracting, with the merge driver handling conflicts..context/: this is the one people forget. It is usually not ignored by default. In a public repository, committing it publishes every note in it. Decide whether the notes are public, then either track them or add.context/to.gitignoreand accept that a fresh clone starts without them.
Either choice is defensible: track .context/ when the notes can be read by anyone with repository access, and ignore it when they cannot. An undecided repository is the failure, because the answer then depends on whoever commits first.
Verify each layer, and read the failures#
Setup is not finished when the commands return without error. Each layer needs a check that proves it works:
serena project health-check "$REPO"
graphify query "what is the entry point of this project"
graphify god-nodes --top 10
readlink "<vault>/Areas/<project>"
git -C "$REPO" status --short
git -C "$REPO" diff --diff-filter=D --name-only HEAD   # must be empty: nothing deleted
The Graphify query is the real proof that the graph is usable. A query that returns a sensible, scoped subgraph means the extraction worked. A query that returns nothing, or a subgraph of unrelated files, means something is wrong with the ignore rules or the extraction, and you should look before trusting any answer.
The health check is the proof for Serena. If it prints a failure, quote the failing line in your status note, and do not describe the layer as working.
The symlink check is the proof for the vault. The read-back target must match the repository's .context/. If it does not, the notes you write will land somewhere else.
Last, check that nothing was deleted. The setup creates files and links, and it should never remove one. An empty diff on deletions is the only evidence that the setup did what it claimed.
Capture, the registry and the review cadence#
A structure with no intake rots in a month. Three mechanisms keep the vault true: a single capture point, a registry that maps every repository, and a review cadence that runs whether or not anyone feels like it.
Capture: cheap at the door, deliberate inside#
Everything unsorted goes to Inbox/ as one note. The minimum is a frontmatter block and the raw content, with no structure required:
---
date: 2026-10-05
description: "Hybrid search over the notes index: is pgvector enough for 2k notes?"
tags: [inbox]
type: resource
status: active
---

Source: https://example.com/article
Idea: the index is one file, so grep works until it does not.
Capture is cheap and classification is deliberate. Never block a capture on deciding where it belongs. The Inbox is allowed to hold items with an explicit reason for staying there.
An agent processing the Inbox does not move items on its own judgement. For each item it produces a RECOMMENDATION: a proposed target, a one-sentence reason and the wikilinks it would attach. It may create a new note in the target when the item is purely additive. It may not restructure, merge, split or reword an item, and it may never touch Archives/. A human disposes of the recommendation.
A project is created only when three conditions hold together: there is a concrete outcome you would recognise as done, it needs more than one work session, and someone owns it. When the project has a repository, the creation is three steps: create <repo>/.context with Project Overview.md and Project Status.md, symlink Projects/<name> (or Areas/<name>) to that .context, and register it.
Agents capture on their own, within a routing table#
Agent Rules.md rule 15 is a standing instruction to write worthwhile things down as they happen, without asking for permission for purely additive notes. Its routing table decides where each thing goes:
| Situation | Destination |
|---|---|
The working repository has a .context | That .context: Decisions/, Tasks/, Notes/ or Project Status.md |
The working repository has no .context | Inbox/, naming the repository path in the body |
| Not project work, obvious PARA home | That location |
| Not project work, unclear home | Inbox/ |
| Work on the vault itself | _System/Logs/ |
What to capture is the part that makes the vault useful: decisions and their reasons, constraints stated once, blocking questions, the cause of a non-obvious fix, and external references worth returning to. What not to capture is just as firm. Anything the code, the tests or git log already say does not belong in the vault, and neither does tool output or conversational scaffolding. Secrets and private client detail never go into a .context, because some of those directories sit inside public repositories. Check before writing, and prefer the vault for anything sensitive.
Search before you decide#
Before a decision is recorded, the vault is searched for earlier ones. The search runs against generated indexes, not against the notes themselves:
IDX="<vault>/_System/Decisions Index.md"
grep -F '**<project>**' "$IDX"                 # every decision in this project
grep -i '<topic>' "$IDX"                       # every project: solved elsewhere?
bash <vault>/_System/bin/build-indexes.sh      # rebuild when stale, about 4 seconds
The third grep is the one that pays. A constraint settled in one repository usually applies to another, and nothing else surfaces it. The rule that follows is strict. If a prior decision covers the same ground, the new note names the earlier one and says why it no longer holds. The earlier note gets status: superseded and superseded-by: pointing at the new one. Silently deciding the opposite is the failure the rule exists to prevent.
The indexes are generated, and the script's own header says they are never hand-edited. The script reads the frontmatter of every note under Projects/ and Areas/, following the symlinks into each repository's .context, and writes one line per decision, note and resource. That is why the frontmatter description matters: it becomes the line the grep finds.
The registry: one entry per repository#
_System/Project Registry.md is the authoritative mapping from each repository-backed effort to its path, its .context, its PARA location and its tooling state. Each entry records the state as observed, and the entries are the record of what each tool does in each repository:
- [[Areas/<project>/Project Overview|<project>]]
  - Repository path: `<repo>`
  - Local context: `<repo>/.context`
  - PARA: `Areas/<project>` (symlink to the local context)
  - Graphify: initialized locally, output in `graphify-out/` at the repo root
  - Serena: initialized locally, MCP server `serena`
  - Status: active
Adding an entry requires that the paths exist. Moving an effort between Projects/ and Areas/ is a symlink move: the link is removed and recreated under the new folder, the notes stay where they are, and the registry entry and every wikilink change with it. The registry note describes the procedure. A move that skips the wikilink update is the case the structural health check exists to catch.
The review cadence#
Review Workflow.md defines four cadences, and each has a time budget:
| Cadence | Scope | Budget |
|---|---|---|
| Daily | Sweep Inbox/: classify each item or park it with a reason | 5 minutes |
| Weekly | For each project with status: active, update Project Status.md, check the outcome is still recognisable, record why anything stalled | 20 to 30 minutes |
| Monthly | For each note in Areas/, check the standard is met and that no project has quietly emerged inside it | 20 minutes |
| Quarterly | List projects with no movement for 90 days; revive each with a next step or propose archiving | As needed |
The review also refreshes Graphify for every registered repository whose code changed, runs a structural health check for broken wikilinks and broken symlinks, and refreshes the Dashboard. The rule for the quarterly pass is the one that is easiest to break: archiving is proposed, never performed. Archives/ is written only by a human.
The cadences are run by a skill, /vault-review daily|weekly|monthly|quarterly|check, which writes a session log and stamps the cadence table on the Dashboard. The review note stays as the definition, and the skill is how it happens. The note records that before the skill existed the cadence table read a dash in every cell.
Know-how from the running setup#
The commands above are the procedure. The details below come from the output of the setup in this repository, read on the day I wrote this article. They are the lines you need when a check does not look like the one in the docs.
Vault: three gotchas recorded in the registry#
These came up in the registry entries, which record what happened to each repository, not what the docs promise.
Code-only extraction can be nearly empty. One registry entry says that for one repository, code-only extraction yielded about five nodes, so semantic extraction was required. It was run against a local model with a token budget set to fit the model's context. The lesson is to check the node count after the first extraction. A near-empty graph is not a working graph, and the registry entry is where the workaround goes.
Serena's config keys are version-sensitive. The same registry records that the languages key in project.yml must not be renamed to language_servers, because the rename breaks one released version of the Python package. The key name is part of the contract with the installed version, so check the release before touching the file.
Symlinked projects need the path form of the wikilink. A plain [[project-name]] does not resolve, because the symlink is a folder and not a note. The link has to name the overview note inside the folder: [[Projects/<name>/Project Overview|<name>]], or the same with Areas/. The structural health check reports the broken ones.
There is also an older vault on the same machine, in a numbered-PARA layout, and the current vault's rules tell agents not to read or write it. Keep one vault as the index. Two vaults that both claim to be the index will drift apart, and an agent will find whichever one its search path reaches first.
Serena: read the verdict, not the log#
serena project health-check prints a large volume of INFO lines, one per task, and most of them are noise. The verdict is the last lines of the output. On this repository it ends with:
Health check completed successfully
✅ Health check passed - All tools working correctly
Keep the full log for a failure. The run writes it to a file under the project's .serena/logs/health-checks/ directory, and that path is printed near the end. When you report the result, quote the verdict line, and if it is a failure, quote the line that names the failing tool, not the whole log.
The health check exercises two tools on a symbol it finds in the project itself. It ran FindSymbolTool on eslintConfig and FindReferencingSymbolsTool on the same symbol. The log shows the TypeScript language server starting, reporting cross-file indexing complete, and then answering both queries. A pass therefore covers more than a process starting, which is why it is the check to trust.
The MCP entry is worth checking separately. claude mcp list shows the exact command the server runs. Here it is:
serena: serena start-mcp-server --context=claude-code --project-from-cwd - ✔ Connected--project-from-cwd is the flag that makes one global registration serve every repository. If you see the server connected but the tools answer about the wrong project, check the working directory the session started in, not the registration.
Serena: the project.yml knobs that matter#
.serena/project.yml is generated with a commented template. Most of its options can stay empty. These are the ones I would look at first:
| Key | What it does | When to change it |
|---|---|---|
activation_command | Shell command run before the language server starts, in the project root | A repository that needs npm install or a codegen step before the language server can resolve imports |
activation_command_timeout | Seconds before that command is killed (default 180) | Only if the activation command is legitimately slow |
line_ending | lf, crlf or native for files Serena writes | Mixed-platform teams; leave unset otherwise |
language_backend | LSP or JetBrains, fixed at startup | Only if you run JetBrains and want its index |
ignore_all_files_in_gitignore | Serena skips what .gitignore excludes | Leave it true, so generated folders that are git-ignored stay out of the index |
ls_specific_settings | Per-language server options | Only when a language server needs a setting to behave |
The activation_command note in the template says the command runs only if the project is trusted, under trusted_project_path_patterns in the global configuration. If an activation command you set never seems to run, check that the project matches those patterns before debugging the command itself.
Git: the ignore lines that prevent noise#
Two groups of generated output need ignore rules. In this repository the lines are:
# serena mcp tool config
.serena

# graphify rotating backup snapshots (dated dirs), regenerated, not source
graphify-out/[0-9][0-9][0-9][0-9]-[0-9][0-9]-[0-9][0-9]/
graphify-out/.rebuild.lock
Graphify keeps dated snapshot directories beside graph.json, and it takes a lock file while it rebuilds. Neither belongs in history. The dated pattern is the important one: it matches only the snapshot folders and leaves graph.json and GRAPH_REPORT.md tracked, which is the split I recommended above.
Graphify: the query output is a budget, not a list#
graphify query runs a breadth-first traversal and returns the nodes it reached within a token budget. On a real question here, the answer header read:
Traversal: BFS depth=2 | ... | 165 nodes found
[!] TRUNCATED: showing 70 of 165 nodes (~2000-token budget).
Two consequences follow. First, the answer may be among the nodes cut off, so the tool tells you to raise the budget with --budget or to narrow the question. Second, a broad question such as "how is blog post data loaded" starts from a cluster of files, not from the one function you need. Narrow it with a concept that exists as a single node, and use explain on that node instead:
graphify explain "getAllPosts"Use query to find the neighbourhood and explain to read a node. Use path when you already know both ends.
Graphify: god nodes are where changes are risky#
graphify god-nodes --top 5 lists the most connected nodes. On this repository the top of the list was:
1. getAllPosts() - 33 edges
2. usePrefersReducedMotion() - 22 edges
3. Profile - 20 edges
4. compilerOptions - 17 edges
5. useEgg() - 15 edges
Read that list as a risk map. A change to a node with 33 edges touches a large part of the code, and it deserves a test before the edit, not after. The list also tells you where to point a new agent first: the hubs are the fastest route to the architecture, and they are the places where a careless edit spreads.
Memories: check the names, not only the count#
serena memories list prints the names of the memories the project holds. Here there are seven: blog, conventions, core, memory_maintenance, suggested_commands, task_completion, tech_stack. The memory_maintenance name is the one seeded by serena memories initialize, and it appears without a project copy when a global one already exists. A missing name tells you more than a count does. If suggested_commands is absent, the agent has no command list written down for this project, so the rules file has to carry the commands instead.
One prompt that sets it all up#
Everything above can be driven by one prompt, pasted into a Claude Code session opened in the repository. The prompt creates the skills the setup relies on, once per machine, and then onboards the repository through them. It asks two questions before it touches anything, and it stops on any conflict.
Run it on a scratch repository first. It writes into the repository, into the vault and into ~/.claude/skills/, and the rules in it are the reason it is safe to run again, not a guarantee that it is correct for your machine.
Set up the full agent toolchain for this repository. Work in phases and stop on any conflict.

Inputs. Ask me once, before anything else, for any that were not given:
- REPO: absolute path (default: the current directory)
- VAULT: absolute path to the Obsidian PARA vault. It must already contain _System/.
- KIND: Project (an outcome with an end) or Area (an ongoing standard, no end)
- PUBLIC: is the repository public on its remote? yes or no

Hard rules:
- Detect before you act. Existing configuration is reported and kept, never recreated.
- Never delete. Never overwrite an existing file. Never rm a symlink. Never use --force or --purge.
- Never run a command that spends API tokens (semantic graphify extraction, graphify label). Ask first.
- Never install a global tool. If serena or graphify is not on PATH, stop and tell me.
- Never commit, never push, never open a pull request.
- Never read or write another repository, or any vault other than VAULT.
- Write only what you observed. Do not invent goals, scope or commands.
- If PUBLIC is yes, nothing secret goes into .context/ or Serena memories.

Phase 0: skills (once per machine, outside the repository)
For each skill below, check ~/.claude/skills/<name>/SKILL.md. If it exists, leave it alone.
If it is absent, create it with YAML frontmatter (name, description). The description says
when to use the skill and that it is idempotent. The body follows the steps given here.

1. project-onboard: runs phases 1 to 3 in order, then consolidates AGENTS.md.
2. serena-onboard:
   - `claude mcp list`. Register only if no serena entry exists: `serena setup claude-code`.
   - `serena project create <REPO> --name <name>` only if .serena/project.yml is absent.
   - `serena project index <REPO>`, then `serena project health-check <REPO>`.
   - `serena memories initialize <REPO>`. Write onboarding memories only for facts you verified
     in the repository, and never invent a command.
3. graphify-onboard:
   - `graphify extract <REPO> --code-only`. Not the semantic mode.
   - `graphify codex install` only if AGENTS.md has no graphify section.
   - `graphify hook install` only if `graphify hook status` shows the hooks absent and no hook
     manager (husky, lefthook, pre-commit) owns .git/hooks. Otherwise report the conflict.
4. obsidian-onboard:
   - Create .context/ with Project Overview.md, Project Status.md, Decisions/, Tasks/, Notes/
     and _System/Context Instructions.md. Create a file only if it is absent.
   - Symlink VAULT/Projects/<name> (KIND Project) or VAULT/Areas/<name> (KIND Area) to
     <REPO>/.context. Read the link back and compare resolved paths.
   - Append one entry to _System/Project Registry.md under "## Active", only if the name is absent.
     Record the tool states you observed, not the ones you intended.
   - Add one line to _System/Dashboard.md, only if absent.

Phase 1: tools
Run the serena steps, then the graphify steps. After each command, quote its verdict line,
for example "Health check passed", or the node and edge count.

Phase 2: vault
Confirm the symlink target. Check that every wikilink you wrote uses the path form
[[Projects/<name>/Project Overview|<name>]] or [[Areas/<name>/Project Overview|<name>]].

Phase 3: rules and decision
- Make AGENTS.md one file with these sections: Commands, Architecture, Project context,
  Serena, Graphify, and "Which tool for which question". Keep existing content and any managed
  <!-- BEGIN:... --> block. Append after such blocks, never inside them. Do not restate what
  graphify codex install already wrote.
- CLAUDE.md must contain only a heading, a one-line pointer and "@AGENTS.md". If it holds other
  substance, show me the diff and wait for my answer.
- Write one dated note in .context/Decisions/ recording KIND and why, the extraction mode, the
  hook status, and anything you deliberately did not run.

Verification. Run these and quote each output:
  serena project health-check <REPO>
  graphify query "what is the entry point of this project"
  readlink <the vault link>
  git -C <REPO> diff --diff-filter=D --name-only HEAD     # must be empty
  git -C <REPO> status --short

Report, per phase: what was created and what was skipped; every failing line verbatim; the
AGENTS.md sections present; the git decisions still open for .serena/, graphify-out/ and
.context/; anything you refused to do and why. Then ask me those git decisions as questions.
Do not decide them yourself.
Three things in that prompt do most of the protecting. The two questions at the start stop the agent from guessing whether the vault is an Area and whether the repository is public. The API-cost rule keeps a semantic extraction from running in the background. And the deletion check at the end is the evidence that nothing was removed, which is the only proof you should accept.
What this does not do#
The three layers do not make the agent correct. Serena tells it where a symbol is, not whether the change is right. Graphify shows the shape of the code, and a graph of the wrong shape is worse than none. The notes are only as good as the discipline of writing them. An empty Project Status.md is not a status report, and a decision that is never recorded is not a decision.
The setup also costs something to keep. The graph hooks run after every commit, the index needs refreshing when the language server changes, and the notes need an update after substantial work. Those costs are small individually, and they add up if nobody owns them. Review the layer state once a month: the health check, the hook status, the symlink, and the registry entry.
Finally, none of this is a substitute for writing good tests, reading the code, or understanding the problem. It is scaffolding. It makes the next session start with the right facts. It does not make the facts right.
The short version#
One rules file, AGENTS.md, with one ordering rule that sends each question to the right layer. Serena for symbols, registered once and health-checked. Graphify for relationships, extracted code-only, with git hooks that keep it current. A .context/ directory for the reasons, symlinked into the vault and registered with the state you actually observed. Three git decisions, written down. Then verify each layer and read the failures instead of skipping them.
$ related posts
· 15 min
Jev as a Claude Code prompt router: routing by task sizeNEW
A Jev classifier in a Claude Code prompt hook sizes each message and routes it to a helper agent. Thresholds, measured cost, and failure modes.
15 min
· 22 min
Why Claude Code Loses Context, and How Obsidian Fixes It
CLAUDE.md design, MCP config, session hooks, and a 5-step interview that generates your agent's operating manual. Not a second-brain guide.
22 min
· 18 min
Ruflo: What a Swarm Layer Adds to Claude Code
A coordination ledger, vector memory, background workers, and agent routing on top of Claude Code: what Ruflo v3 does, what it costs, and when to skip it.
18 min